Migrating from AlphaGenome 1#
Both models are available through the alphagenome package:
from alphagenome.models.v2 import dna_client  # AlphaGenome 2 (recommended)
from alphagenome.models.v1 import dna_client as dna_client_v1  # AlphaGenome 1
When to use each model#
Use AlphaGenome 2 for most analyses: predicting tracks or scoring variants in a reference condition (
condition=) or under expression conditioning on your own human scRNA-seq count matrix (cell_conditioning=), predicting single-cell accessibility (SC_ATAC), denoised single-cell gene expression (SC_GENE_EXPRESSION_DENOISED), protocol-specific single-cell gene expression (SC_GENE_EXPRESSION), or CpG methylation (METHYLATION), computing input gradients for enhancer-to-gene (E2G) attribution (predict_interval_gradients), encoding single-cell profiles (encode_cells), or using cross-modality track imputation.Use AlphaGenome 1 to reproduce results from the AlphaGenome paper [Avsec et al., 2026], score variants across all tissues and cell types at once without choosing a condition, or predict PRO-cap tracks.
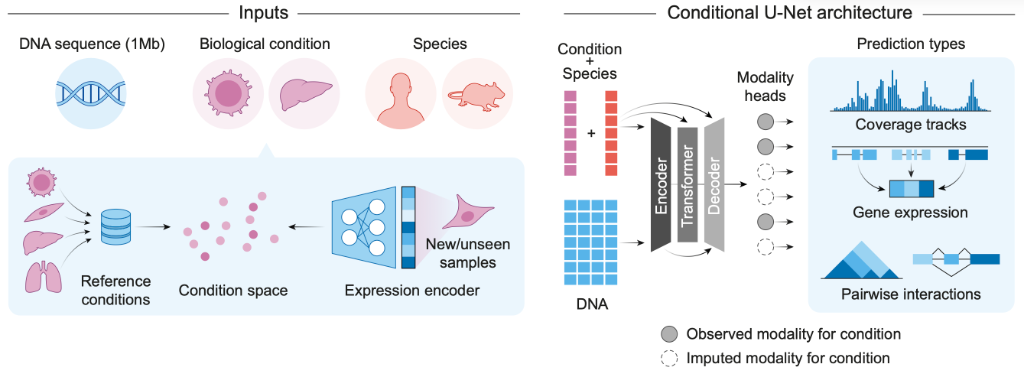
AlphaGenome 2 architecture. Takes a DNA sequence of up to 1 Mb, the species, and a condition (a reference condition, or a cell embedding from the cell encoder under expression conditioning) to predict observed and imputed coverage tracks, gene expression, splicing, and contact maps.#

AlphaGenome 1 architecture. Takes a DNA sequence of up to 1 Mb and predicts observed multi-task coverage tracks, splicing, and pairwise contact maps across human and mouse assays.#
API migration reference#
Both models share the same core prediction and scoring methods; the differences are in how you choose conditions, discover metadata, and read scores.
Conditions#
AlphaGenome 1 |
AlphaGenome 2 |
|
|---|---|---|
Predict or score one variant or interval |
|
Required: one reference condition ( |
Batch methods ( |
|
One reference condition ( |
Condition format |
Single ontology CURIE |
Composite condition (ontology CURIEs joined by underscores), single
CURIE, or a |
Metadata#
AlphaGenome 1 |
AlphaGenome 2 |
|
|---|---|---|
What can I predict? |
|
|
Which tracks were measured? |
Same table |
|
Biosample column |
|
|
Output types#
Added in AlphaGenome 2 (see Model output metadata for descriptions):
SC_GENE_EXPRESSION_DENOISED: denoised single-cell gene expression undercell_conditioning=, one channel per strand in CPMSC_GENE_EXPRESSIONSC_ATACMETHYLATIONCELL_EMBEDDINGS
Changed in AlphaGenome 2
SPLICE_SITES: the 4 condition-agnostic tracks of AlphaGenome 1 are now condition-specific, with 5 channels per condition (donor +,acceptor +,donor -,acceptor -,padding .).CONTACT_MAPS: targets are not coarse-grained, so values are not directly comparable to AlphaGenome 1 contact maps.
Removed in AlphaGenome 2
PROCAP: useCAGEfor transcription start site activity.
Variant scores#
AlphaGenome 1 |
AlphaGenome 2 |
|
|---|---|---|
Score columns |
|
|
How empirical quantile scores work in AlphaGenome 1
Different output types yield raw variant scores on different scales (for
example, splice site usage scores lie in \([0, 1]\) whereas RNA-seq log-fold
change scores are signed and not restricted to that range). AlphaGenome 1
(alphagenome.models.v1) estimates a background distribution for each
recommended scorer and track across ~300,000 common variants (MAF > 0.01 in any
gnomAD v3 population; see [Avsec et al., 2026]) and converts each raw score
into a percentile rank bounded by ±0.99999.
For signed variant scorers, \([0, 1]\) rank probabilities are linearly mapped to \([-1, 1]\) so that negative scores map near \(-1\), scores near zero map to \(0\), and strongly positive scores map near \(+1\).
Key behavioral differences#
One condition per call: With AlphaGenome 2, each call to
predict_sequence,predict_interval,predict_variant, orscore_variantpredicts for one condition; loop over conditions when comparing multiple tissues or cell types (or pass one reference condition or expression-conditioning input per item to the batch methods).Complete channel output with per-track imputation labels: For every condition, AlphaGenome 2 predicts all channels across requested output types and labels each track in
.metadata['imputation_mode']asobserved,imputed_supported, orimputed_exploratory(see Navigating imputed tracks).